
COA and batch documentation
Peptides vs Proteins: Chain Length, Folding, and Functional Context
A clean educational article explaining peptide bonds, amino-acid chain length, polypeptides, protein folding, and why definitions depend on structure and context.
This article frames peptides, polypeptides, and proteins as a research-use literature topic, focusing on model systems, measured endpoints, documentation context, and evidence limits.
Research context
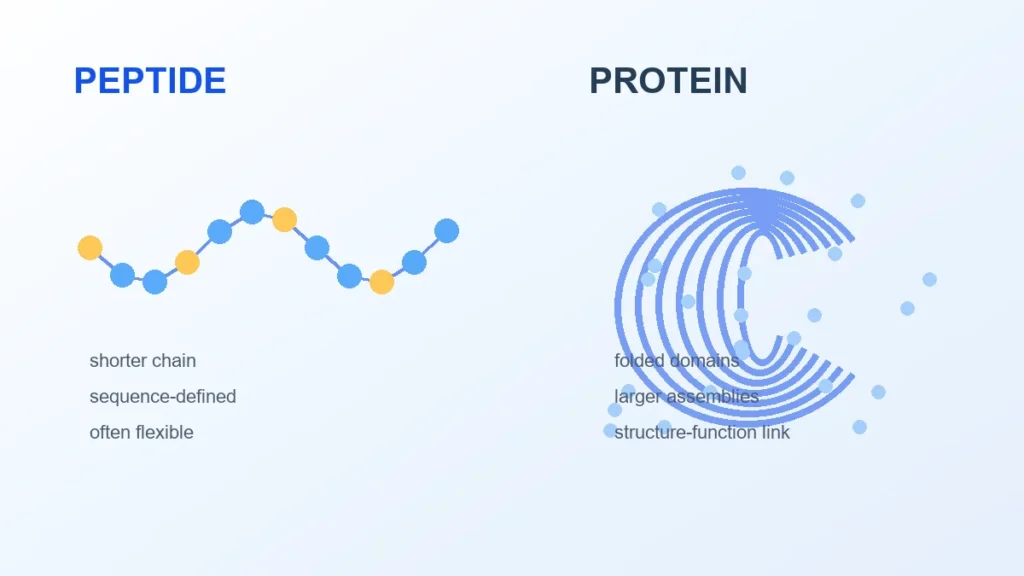
Peptides and proteins are both built from amino acids linked by peptide bonds. The distinction is usually practical rather than absolute: chain length, folding, domain structure, and biological role all matter.
This article frames dipeptides, oligopeptides, polypeptides, folded protein domains, sequence-to-structure relationships, and analytical identification as a research-use literature topic, focusing on model systems, measured endpoints, documentation context, and evidence limits.
Adria research-use note
This article is a literature overview for lawful research settings only and should not be read as practical, consumer, or applied-use guidance.
How to read this research
The peptide-versus-protein distinction is clearest when organized by amino-acid count, folding state, domain formation, functional role, and analytical method.
A concise article can still add value by explaining why the boundary is practical rather than absolute and why sequence documentation matters for both peptides and proteins.
Evidence checkpoints for this topic
Peptides vs Proteins is most useful in the archive when it is read through analytical documentation, peptide identity, storage, formulation, purification, and traceability.
In this article, sources such as NCBI Bookshelf: amino acids and peptide bonds, NCBI Bookshelf: protein structure and folding, Biopharmaceutical benchmarks 2014 should be read for their specific methods, endpoints, and limits.
- Model: check the material record: sequence, batch number, analytical method, storage condition, excipient context, and handling window.
- Endpoint: record identity confirmation, purity profile, HPLC/LC-MS style documentation, formulation notes, stability risk, and chain-of-custody records.
- Comparator: verify whether a statement is based on supplier documentation, analytical method, shipping condition, or a literature source.
- Documentation: keep sequence identity, batch traceability, COA context, storage condition, and source link together.
- Limit: keep visible why procurement and documentation articles should be operationally specific instead of promotional.
What a careful reader can take from it
The practical value of this post is the structure it gives to the literature. Instead of treating every source as equal, the reader can separate the question being asked, the method used to ask it, and the claim that can reasonably follow. That is especially important in peptide topics, where online summaries often compress receptor data, model endpoints, supplier documentation, and broad interpretation into one sentence.